
The batch API is 50% off and your cron jobs don't know
Both major providers sell the same tokens at half price for anything that can wait a few hours. The three-question test for what belongs there.
There is a standing 50% discount on LLM tokens that most teams pay full price to avoid using. Both Anthropic and OpenAI run batch endpoints: submit a file of requests, get results within a day (usually much faster), pay half. That is the whole product. Half.
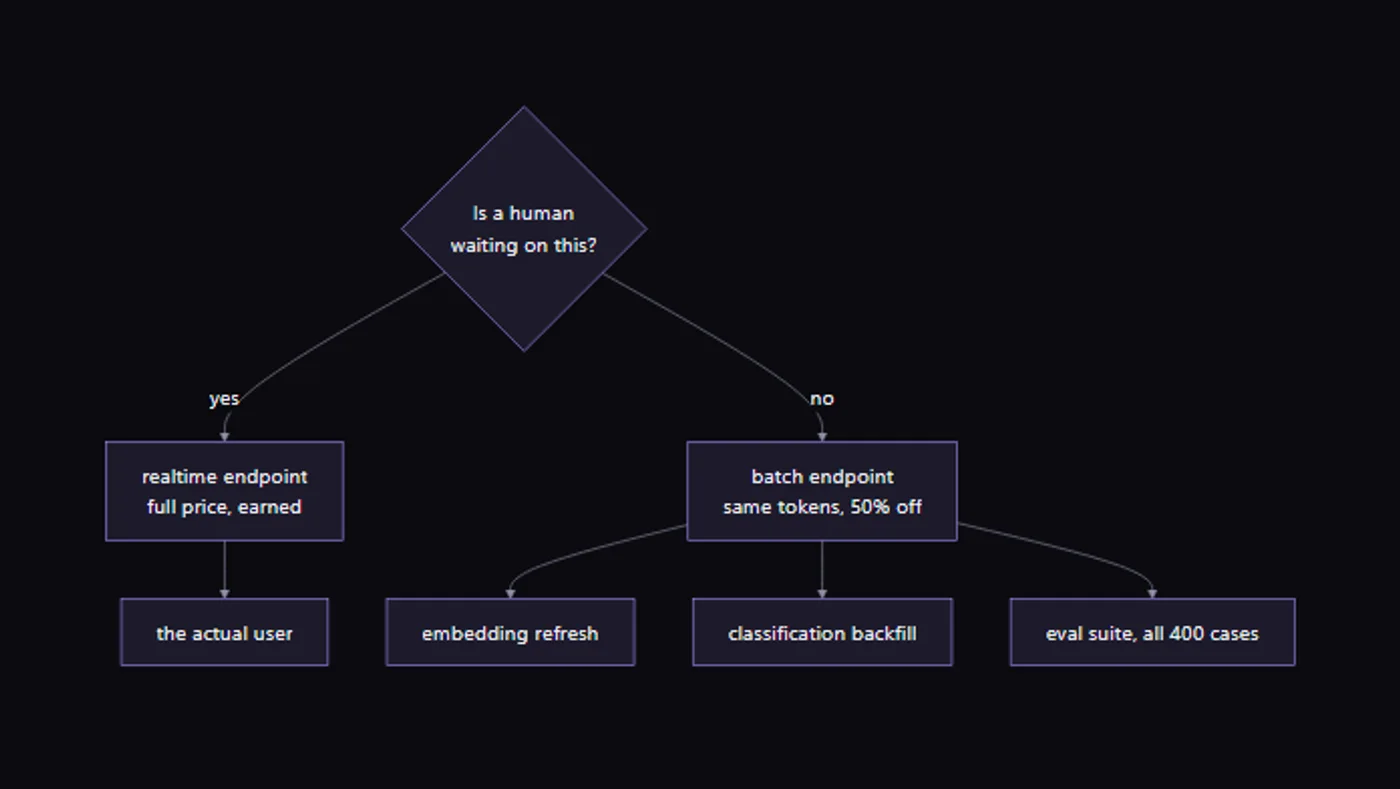
The test for what belongs there is one question asked three ways. Is a human waiting on this response? Your nightly embedding refresh: no human waiting. The classification backfill over eighteen months of tickets: no. The eval suite grinding four hundred cases after every prompt change (you have one, right): no human is waiting on case 217. All of it is running through your realtime endpoint right now at 2x the necessary price, because the realtime endpoint is what the first engineer wired up and cost review never revisited the plumbing.
The gotchas, so you hit them here instead of in prod: results arrive unordered, so carry your own IDs. The completion window is a ceiling, not an estimate; design the consumer to tolerate the ceiling even though you'll usually beat it. And batch jobs fail per-line, not per-file, so the retry logic handles partial results or you rediscover distributed systems the annoying way.
The audit is genuinely thirty minutes: list every LLM call site, mark which ones have a human on the other end, and move the rest. On the workloads I've moved this year the blended bill dropped 20-30% for one afternoon of plumbing, which beats every prompt-golf optimization on the same bill by an order of magnitude of effort.
Same tokens. Same models. Half price for patience. Your cron jobs have infinite patience. Introduce them.